
A common advisor bug is not a bad model response; it is a request that changed before the model call. One advisor adds context, another rewrites the prompt, and the final request no longer resembles the original ChatClient call.
To debug that path, record three things for one synchronous request: each advisor’s entry and exit, the exact prompt reaching the model, and whether the downstream call returned normally. Those observations explain both reverse response order and missing after() callbacks.
This article examines Spring AI 2.0.1 with a local recording model. The fixture is intentionally small: it makes order, prompt mutation, short-circuiting and exception behavior visible without a provider key.
What an Advisor Actually Surrounds
Consider a familiar client call:
String answer = chatClient.prompt()
        .user("Explain database transactions.")
        .call()
        .content();
The configured model does not necessarily receive the user message unchanged. Advisors can inspect or transform the request before it reaches the model.
An advisor may:
- Add conversation history.
- Append retrieved evidence.
- Rewrite a question.
- Inspect request context.
- Reject a request.
- Process the returned response.
The relevant objects are:
| Object | Role |
|---|---|
ChatClientRequest | Carries the prompt and advisor context |
ChatClientResponse | Carries the model response and advisor context |
CallAdvisorChain | Provides access to the next synchronous processing stage |
Advisor context and prompt content serve different purposes. A value placed in context is available to application-side processing; it does not automatically become text that the model reads.
For example, a conversation ID can select stored history without being included in the user-facing question.
Start with the Source, Not the Registration List
Three source locations explain most of the ordinary synchronous flow:
| Source | Relevant method or area | Responsibility |
|---|---|---|
| DefaultAroundAdvisorChain | Advisor sorting and nextCall() | Select and invoke the next advisor |
| BaseAdvisor | adviseCall() | Provide the standard before/delegate/after structure |
| ChatModelCallAdvisor | adviseCall() | Hand the processed prompt to ChatModel.call() |
Conceptually, a synchronous advisor can behave like this:
ChatClientRequest updatedRequest = before(request);

ChatClientResponse response =
        chain.nextCall(updatedRequest);

return after(response);
This is explanatory pseudocode, not a replacement implementation of the framework.
The important operation is nextCall(). It transfers control to the next advisor. That downstream processing must return before the current advisor can continue with its response handling.
Why Responses Return in Reverse Order
Assume two advisors delegate normally:
- Advisor A has order
10. - Advisor B has order
20.
The diagram follows one successful synchronous interaction. Read it from top to bottom: requests move toward the model, and responses return through the waiting advisors.
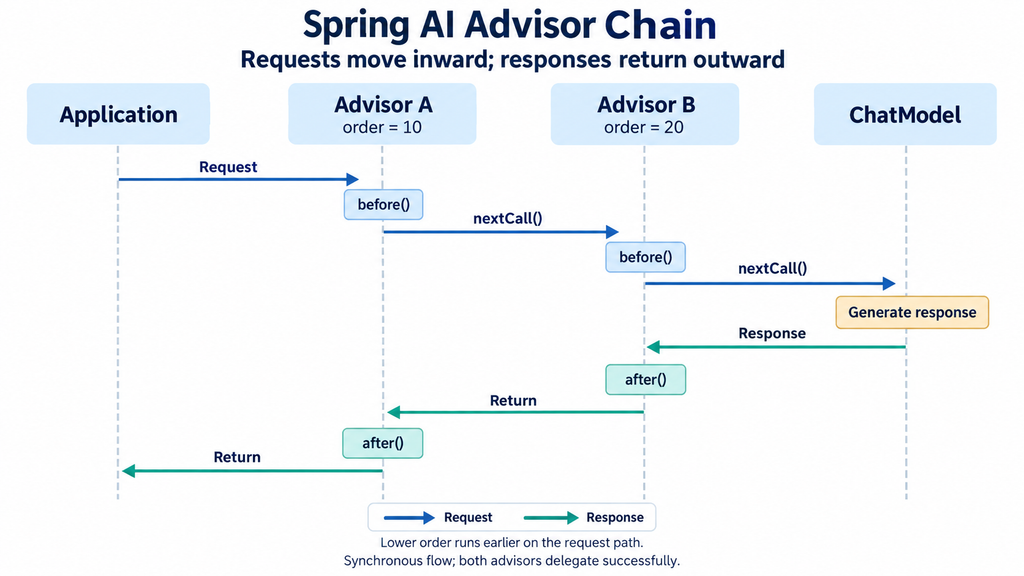
Figure 1. Advisor A enters first, but Advisor B processes the returning response first. Synchronous flow; both advisors delegate successfully. Other framework advisors are omitted for clarity.
A enters first and calls the next stage. B then enters and eventually reaches the model.
When the model returns, execution resumes inside B. Only after B finishes does A receive the downstream response.
There is no need for a separate reverse-order loop to produce this behavior. It follows from the nested calls.
This also explains which response an advisor sees: if B changes the response, A receives B’s returned version.
The model-facing advisor is the final model handoff in this ordinary path. An earlier advisor can still stop the chain before that handoff.
Execution Order Is Not Simply Registration Order
This configuration can be misleading:
.defaultAdvisors(tagAdvisor, wrapAdvisor)It looks as though tagAdvisor must execute first.
However, the chain sorts advisors by their order values. For the distinct values in our example, the lower numerical value executes earlier on the request path. Advisor chain implementation
Use explicit, distinct values when one advisor depends on another.
The values 10 and 20 below are illustrative. They describe the relationship between our two custom advisors, not their position relative to every built-in advisor.
A Small Example That Makes Ordering Observable
We will use two text transformations:
wrapsurrounds the current user text with square brackets.tagappends an exclamation mark.
The advisor records its entry and exit:
record TransformAdvisor(
        String name,
        int order,
        UnaryOperator<String> transform,
        List<String> trace) implements BaseAdvisor {

    @Override
    public String getName() {
        return name;
    }

    @Override
    public int getOrder() {
        return order;
    }

    @Override
    public ChatClientRequest before(
            ChatClientRequest request,
            AdvisorChain chain) {

        trace.add(name + ".before");

        String text =
                request.prompt().getUserMessage().getText();

        return request.mutate()
                .prompt(request.prompt()
                        .augmentUserMessage(
                                transform.apply(text)))
                .build();
    }

    @Override
    public ChatClientResponse after(
            ChatClientResponse response,
            AdvisorChain chain) {

        trace.add(name + ".after");
        return response;
    }
}
This example uses BaseAdvisor, which supplies the normal delegation between before() and after().
Notice that before() returns the updated request. Constructing an updated request and then returning the original would discard the intended change.
The response method is deliberately pass-through. Its trace entry reveals the return order without changing the answer.
Use a Recording Model to Inspect the Final Prompt
A remote model is unnecessary for this experiment. We want to inspect request processing, not evaluate generated text.
The local model records its input and returns a fixed response:
final class RecordingModel implements ChatModel {

    final List<Prompt> requests = new ArrayList<>();
    final List<String> trace;

    RecordingModel(List<String> trace) {
        this.trace = trace;
    }

    @Override
    public ChatResponse call(Prompt prompt) {
        requests.add(prompt);
        trace.add("model");

        return new ChatResponse(List.of(
                new Generation(
                        new AssistantMessage("ACK"))));
    }
}
This is a sequential test fixture. Its mutable lists are not intended for concurrent production use.
Now create the advisors and deliberately register them in the opposite order:
var trace = new ArrayList<String>();
var model = new RecordingModel(trace);

var wrap = new TransformAdvisor(
        "wrap",
        10,
        text -> "[" + text + "]",
        trace);

var tag = new TransformAdvisor(
        "tag",
        20,
        text -> text + "!",
        trace);

ChatClient client = ChatClient.builder(model)
        .defaultAdvisors(tag, wrap)
        .build();

String answer = client.prompt()
        .user("hello")
        .call()
        .content();
The previously executed local test against Spring AI 2.0.1 produced this trace:
wrap.before
tag.before
model
tag.after
wrap.after
The recorded user message was:
[hello]!The returned answer was:
ACKThe trace lists only our instrumented advisors and model. It is not an inventory of every framework component participating in the request.
Run the Test from a Fresh Project
Use a fresh Maven project with Java 17 or newer. Add the Spring AI client module, or manage it through the Spring AI 2.0.1 BOM in an existing Spring Boot project:
<dependency>
    <groupId>org.springframework.ai</groupId>
    <artifactId>spring-ai-client-chat</artifactId>
    <version>2.0.1</version>
</dependency>
Put RecordingModel, TransformAdvisor and the test fixture under src/test/java. Name the test AdvisorOrderTest and run it with:
mvn -q -Dtest=AdvisorOrderTest testThe useful assertions check the trace, the prompt captured by the model and the fixed response:
assertEquals(
    List.of("wrap.before", "tag.before", "model",
            "tag.after", "wrap.after"),
    trace);
assertEquals("[hello]!", model.requests.get(0)
    .getInstructions().get(0).getText());
assertEquals("ACK", answer);
A successful local run should report:
Tests run: 1, Failures: 0, Errors: 0This fixture verifies advisor ordering and request transformation with a local model. It does not prove provider behavior, streaming lifecycle, concurrent safety or the order of unrelated built-in advisors.
Swap the Orders and Compare the Prompt
Assign tag order 10 and wrap order 20.
The transformations now occur in this sequence:
hello
hello!
[hello!]
The model receives:
[hello!]Compare the two configurations:
| Request order | Text reaching the model |
|---|---|
| Wrap, then tag | [hello]! |
| Tag, then wrap | [hello!] |
The difference is deterministic. It exists before the model generates anything.
In a real application, the transformations might insert retrieved evidence or rewrite a follow-up question rather than add punctuation. The dependency is the same: a downstream advisor sees the request returned by the upstream advisor.
Connect This Back to Chat Memory
A memory advisor is one participant in this chain.
In the synchronous path, MessageChatMemoryAdvisor loads retained history, combines it with the current prompt and performs memory updates around downstream processing. Its placement therefore determines what request it receives and what response returns to it. Memory advisor source If history appears to be missing, compare the advisor order with the captured prompt; the related chat memory troubleshooting example uses the same evidence-first approach.
For each advisor, ask:
- What does it read?
- What does it modify?
- What does it save?
- Which other advisor depends on that output?
These questions are more useful than assuming that every advisor processes all available information.
For example, placing memory before retrieval does not automatically make retrieval conversation-aware. In QuestionAnswerAdvisor, the search query is derived from the current user message. A question such as “What about the second option?” may still require a separate query-rewriting operation. Retrieval advisor source
Order determines access to earlier transformations. It does not create behavior an advisor does not implement.
after() Is Not Guaranteed Cleanup
The synchronous BaseAdvisor implementation invokes after() after the downstream call returns. It does not place that invocation in a finally block. BaseAdvisor source
In the local failure test, the recording model throws an exception. The trace becomes:
a.before
model
There is no a.after.
This has two practical consequences.
First, do not rely on after() alone for cleanup that must happen on both success and failure. Such work needs an explicit error-aware lifecycle, such as appropriate try/finally handling around synchronous delegation.
Second, side effects performed before delegation are not automatically undone. If an advisor saves data and the model subsequently fails, that earlier write may remain.
That connects directly to the retry behavior discussed in the Chat Memory article: retrying a failed interaction is not necessarily equivalent to starting from an unchanged state.
An Advisor Can Stop the Chain
An advisor is not required to delegate in every situation.
A custom CallAdvisor can return a response directly. The following is an illustrative control flow:
if (cachedResponseIsUsable(request)) {
    return cachedResponse;
}

return chain.nextCall(request);
The helper and response are application-defined; this is not a complete cache implementation.
If B returns directly in a chain containing A, B and C:
A enters
    B returns a cached response
A resumes with that response
C and the model do not execute. A can still process the response because its downstream call returned normally.
This behavior explains why a client interaction may succeed without producing a model invocation.
For a real cache, correctness depends on the cache key and validity rules. A question alone may be insufficient if the answer depends on tenant, conversation history, permissions or document version.
The short-circuit discussion is source-based explanation, separate from the executed ordering tests.
Streaming and Tool Loops Need Their Own Trace
The examples above cover synchronous calls.
A streaming response has a different lifecycle, including subscription, response chunks, errors and cancellation. Do not assume the synchronous after() behavior describes every streaming advisor.
Tool calling introduces another distinction: repeated downstream execution.
In Spring AI 2.0.1, the tool advisor can invoke the downstream chain for multiple model rounds. An advisor inside that portion of the chain may therefore run more than once during one client interaction. ToolCallingAdvisor source
This matters for retrieval cost, logging volume and stateful processing.
The next article will follow that loop from a model-generated tool request to Java execution and back.
A Practical Debugging Checklist
When advisor behavior is unexpected, inspect the chain before changing the model:
| Symptom | First check |
|---|---|
| Prompt transformations appear in the wrong order | Actual getOrder() values |
| A request change disappears | Whether the modified request is returned |
| An advisor does not see expected data | What earlier advisors write and what this advisor reads |
| Response handling never runs | Downstream exceptions or short-circuit placement |
| No model call occurs | An earlier advisor returning directly |
| Processing happens repeatedly | Tool loops, repair loops or application retries |
For synthetic tests, capturing the complete prompt is convenient. In production, prefer request identifiers, advisor names, message counts and redacted diagnostics over logging entire conversations.
Conclusion
Spring AI advisors form a chain of nested processing stages. Requests move through delegation; responses return through the advisors that delegated successfully.
The ordering example demonstrates why placement matters: changing two order values changes the prompt before generation begins. The failure example shows a different boundary: response hooks do not automatically run when downstream execution throws.
For a production incident, keep the request ID, advisor names, order values, prompt fingerprint and downstream exception together. That record distinguishes a wrong order from a discarded request mutation or a response hook skipped by failure.
[…] Spring AI Advisor Chain: Request and Response Order Explained […]